Compression
ProcessResults
The problem
0/125 Builds · 0 Days
Model compression
Smaller and faster, same accuracy, on the devices you own.
Model deployment
One build, every device, from phones to servers.
Five industries where the model has to fit the hardware in the field, and run without the cloud.
 Public sector and defense Air-gapped sites, accredited hardware, no cloud.
Explore Public sector
 Automotive One build across every vehicle platform.
Explore Automotive
 Industrial and robotics Models that fit embedded boards on the floor.
Explore Industrial
 Personal AI computers Your model on every engine in the box.
Explore Personal AI
 Telecommunications The same model from the core to the cell site.
Explore Telecom
Trusted by
Compress, benchmark, deploy and manage, in one platform.
Run your models on phones, edge devices and cloud instances. Compare speed, memory and accuracy side by side.
Explore Benchmarking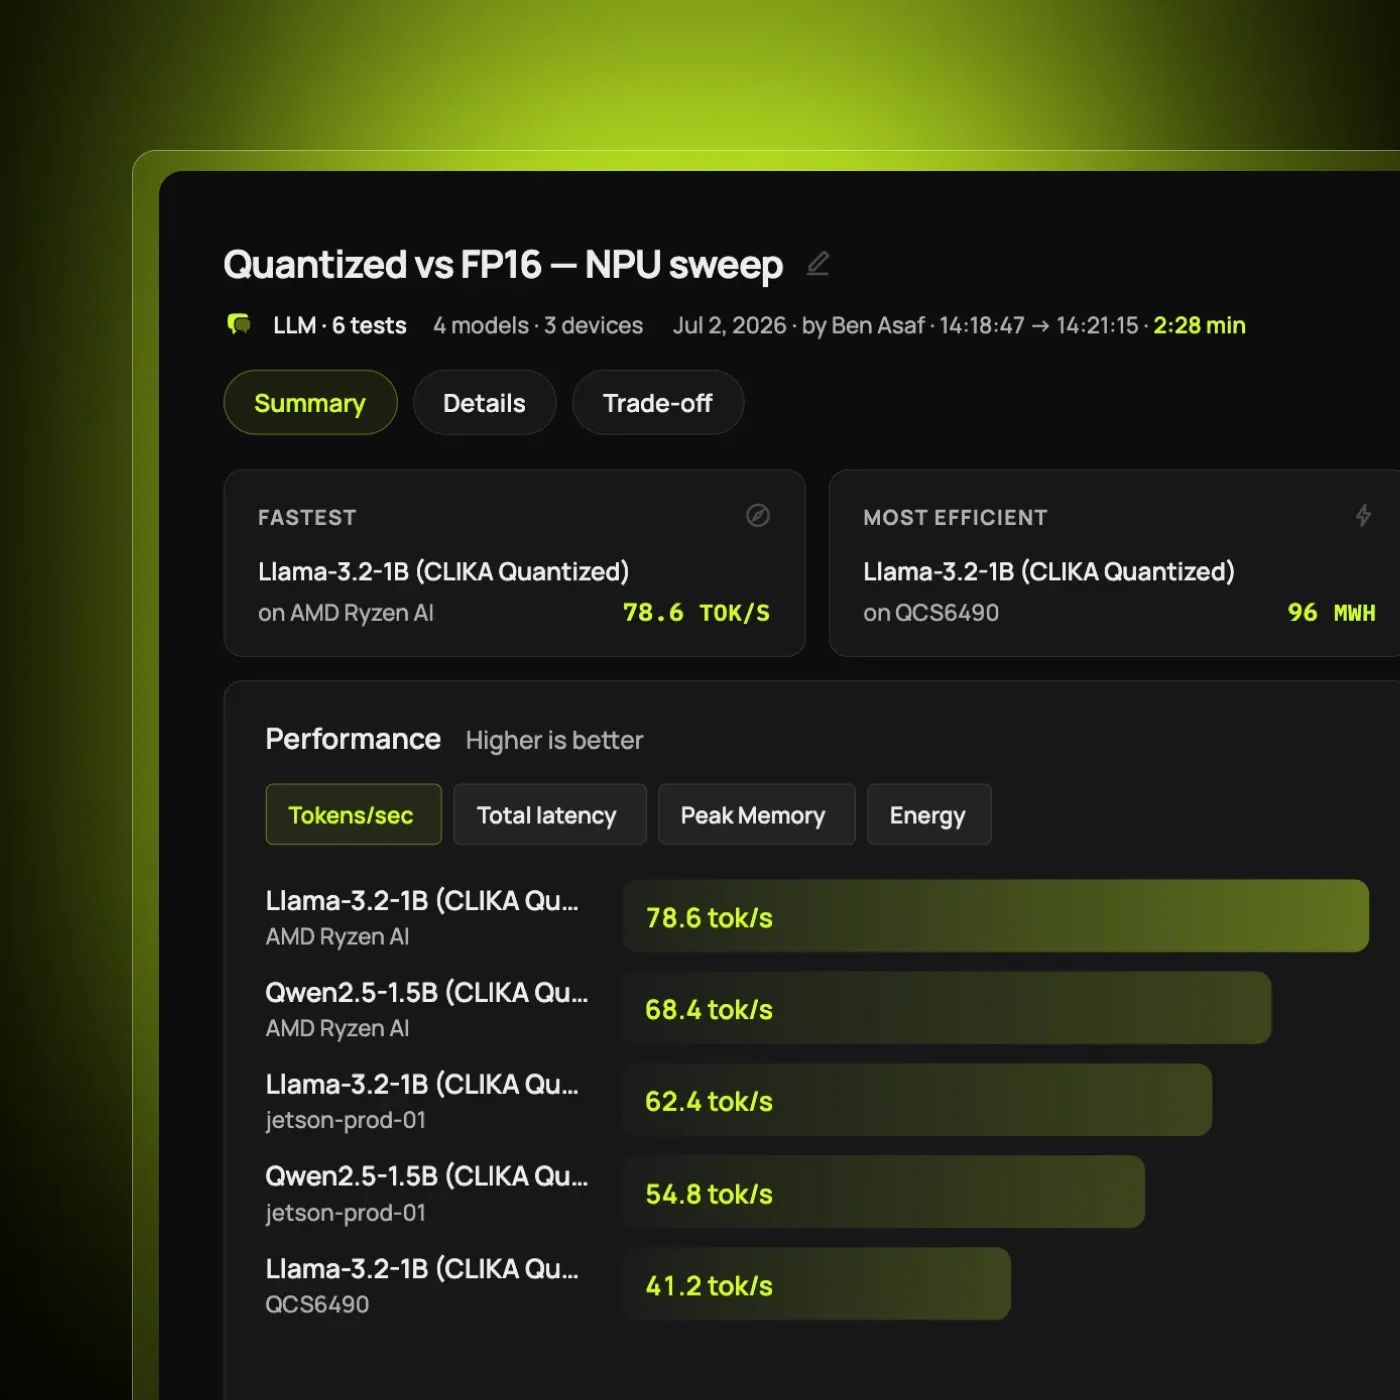
No repackaging, no new pipeline. Deploy your model as an API ready to call, or run it inside your app on the device.
Explore Deployment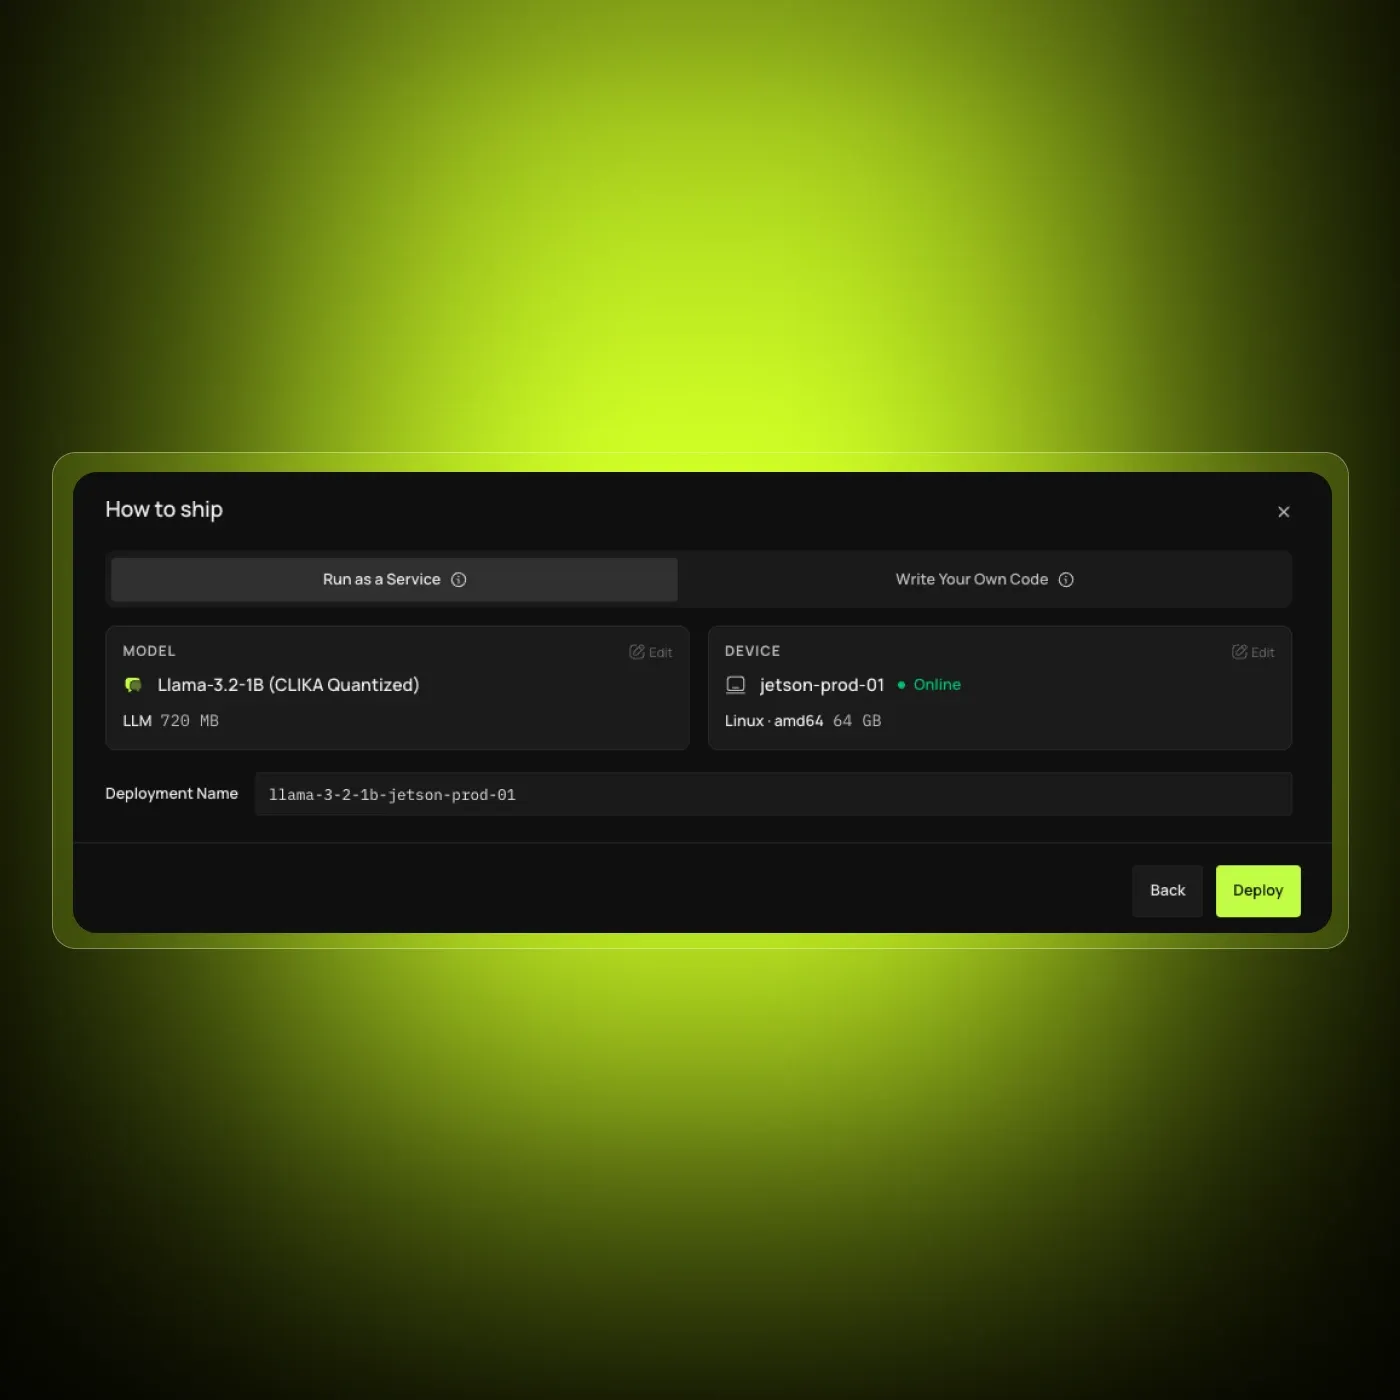
Enroll a device in seconds, then run workloads, watch its health and take control, all from one place.
Explore Device Management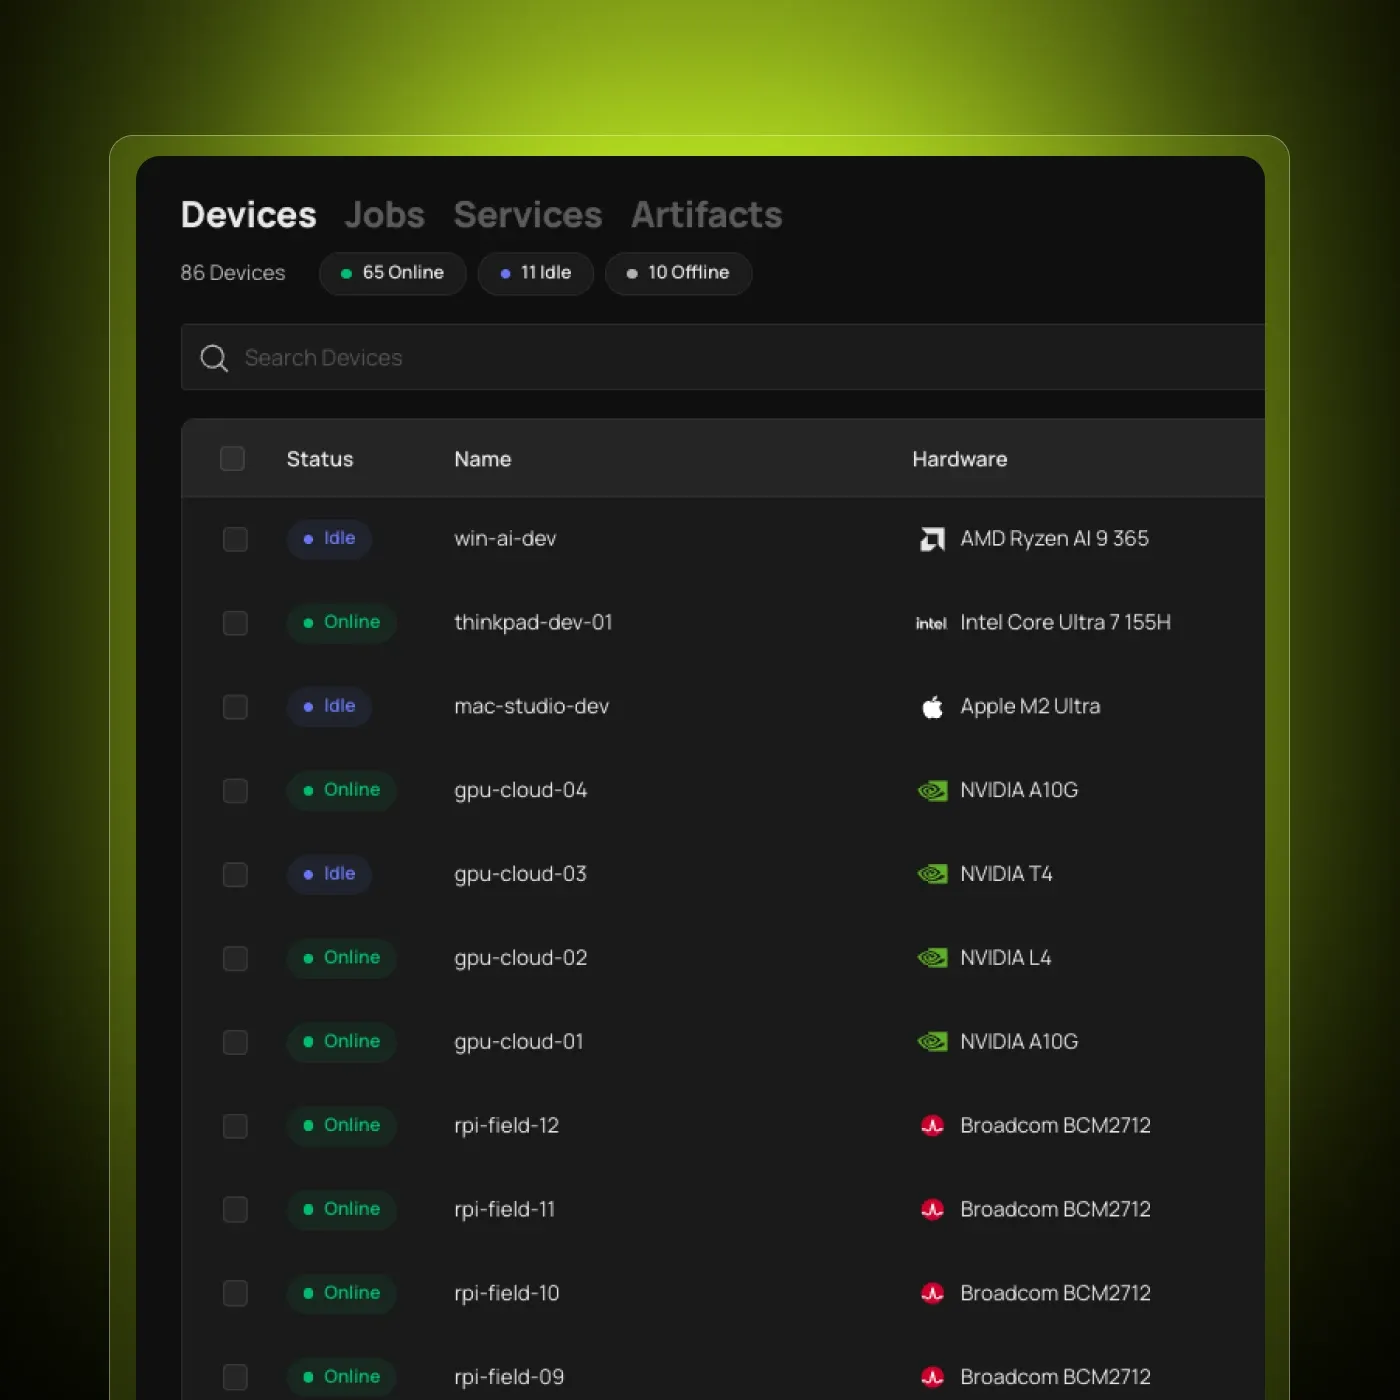
The model you already have, compressed to fit the device you ship, with the accuracy you validated.
x86, ARM and GPU run the same build, with the same results on every device.
Our own engine under the hood. Change hardware, vendor or generation without rewriting the AI stack.
From the first benchmark to the running fleet, everything runs inside your network.
Leave your email and we will get you in.