Compression
ProcessResults
Deploy
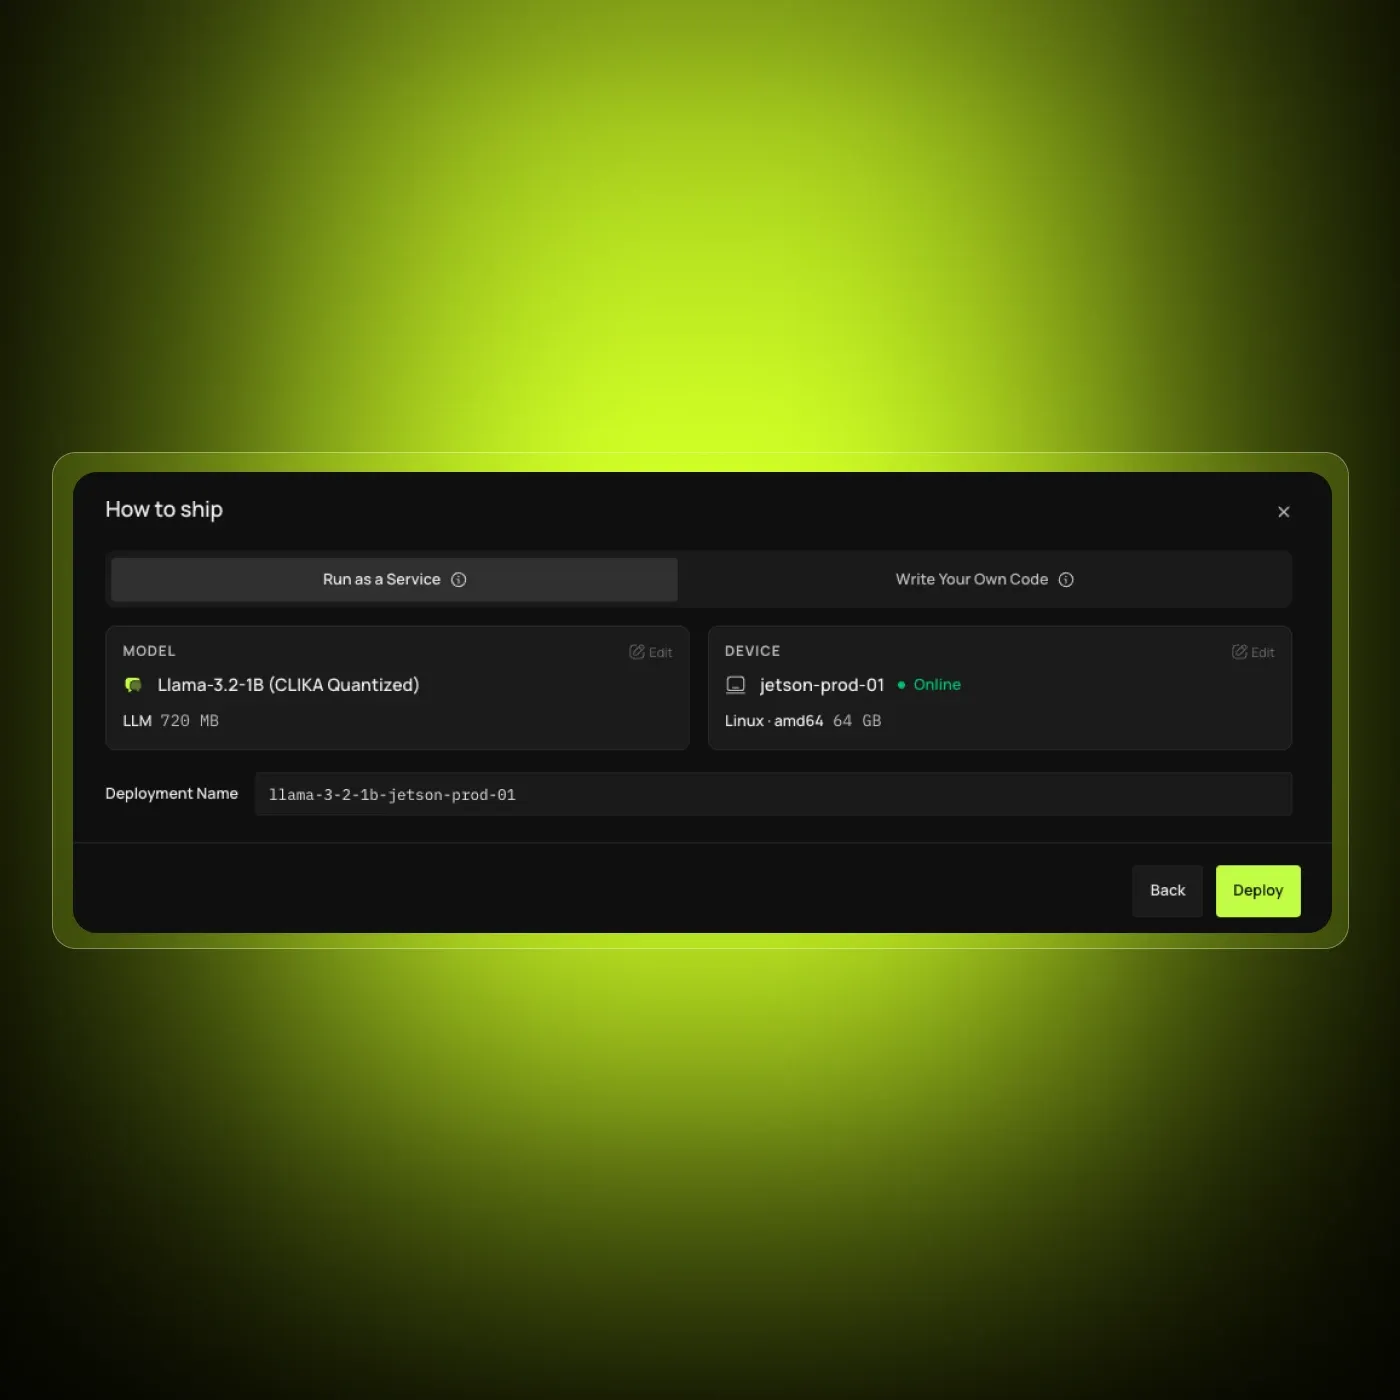
Run it as a service with an API ready to call, or build it into your app with the SDK. Same optimized model either way, on the device you choose.
From benchmark to deployment
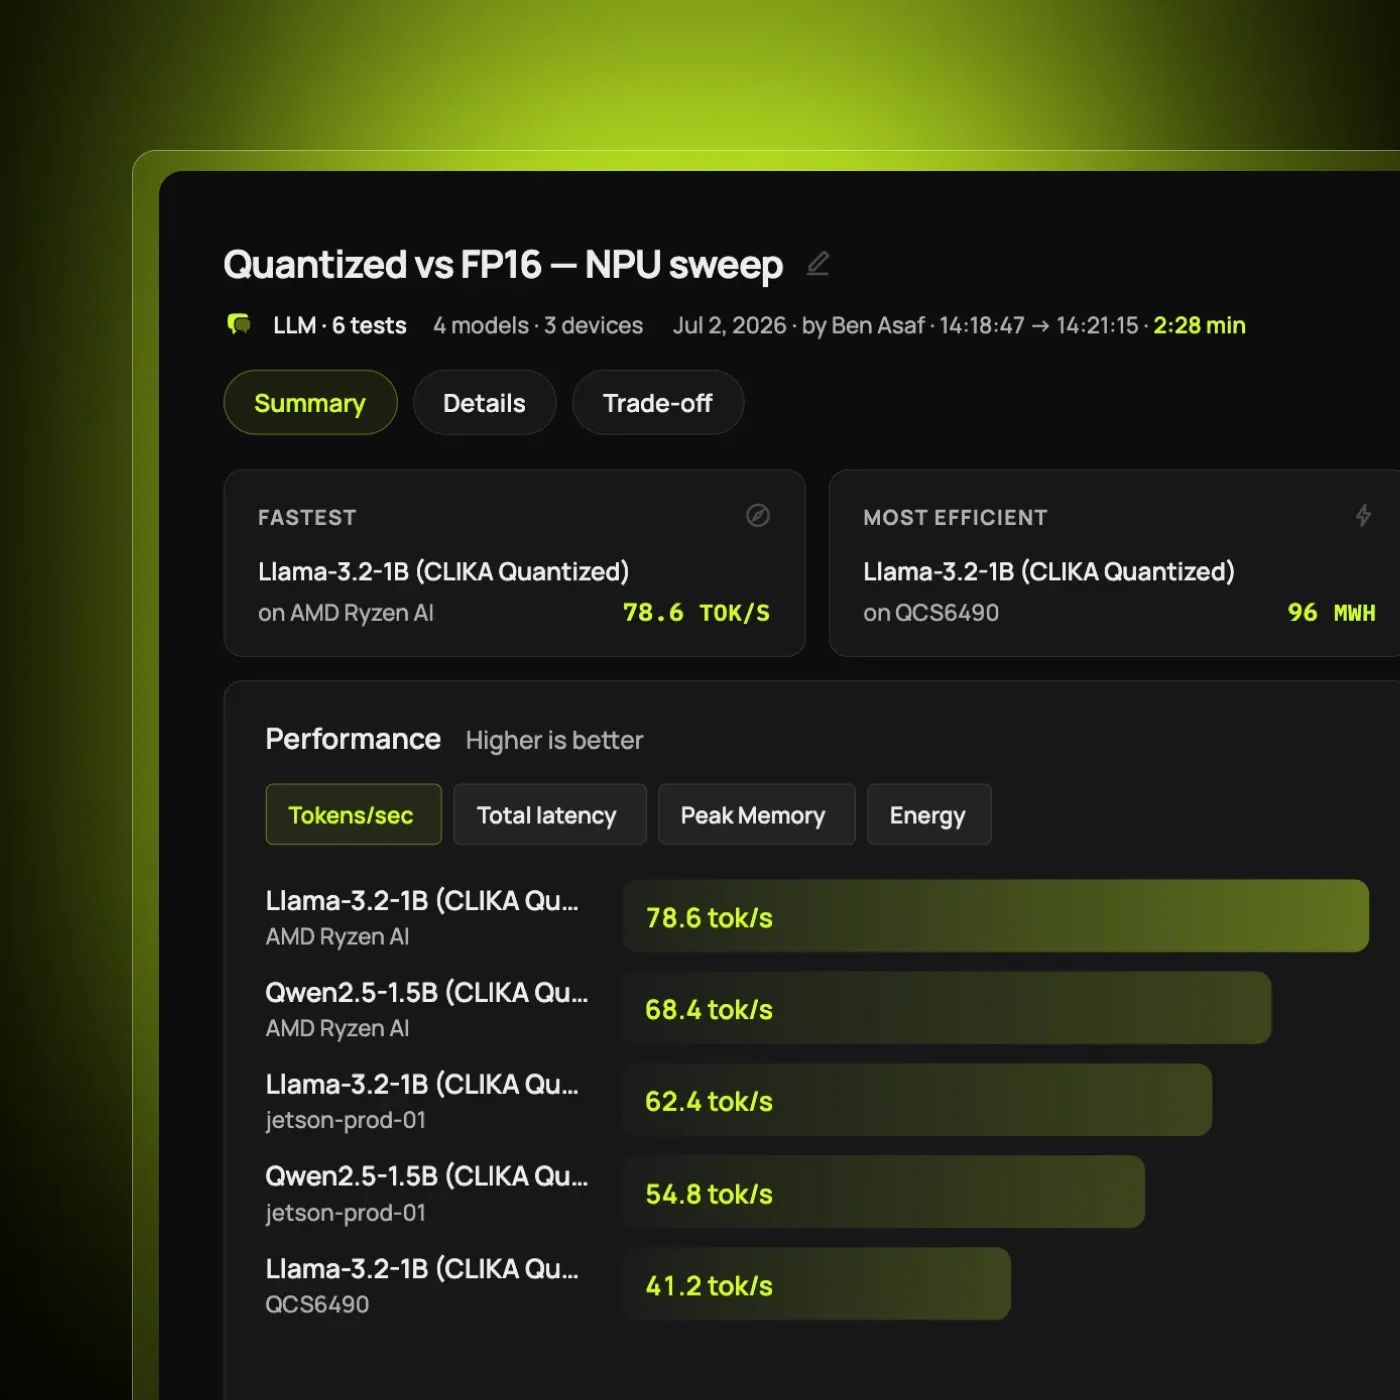
Deploy straight from a benchmark result: pick the model and device pair that won, with nothing to set up again. Or start from any model and any device in your fleet.
Service or SDK
Let the platform start the inference server on your device, or build the model into your app with the SDK for Kotlin, Swift, Flutter, C++ and Python. The same optimized runtime runs either way.
Call it, try it
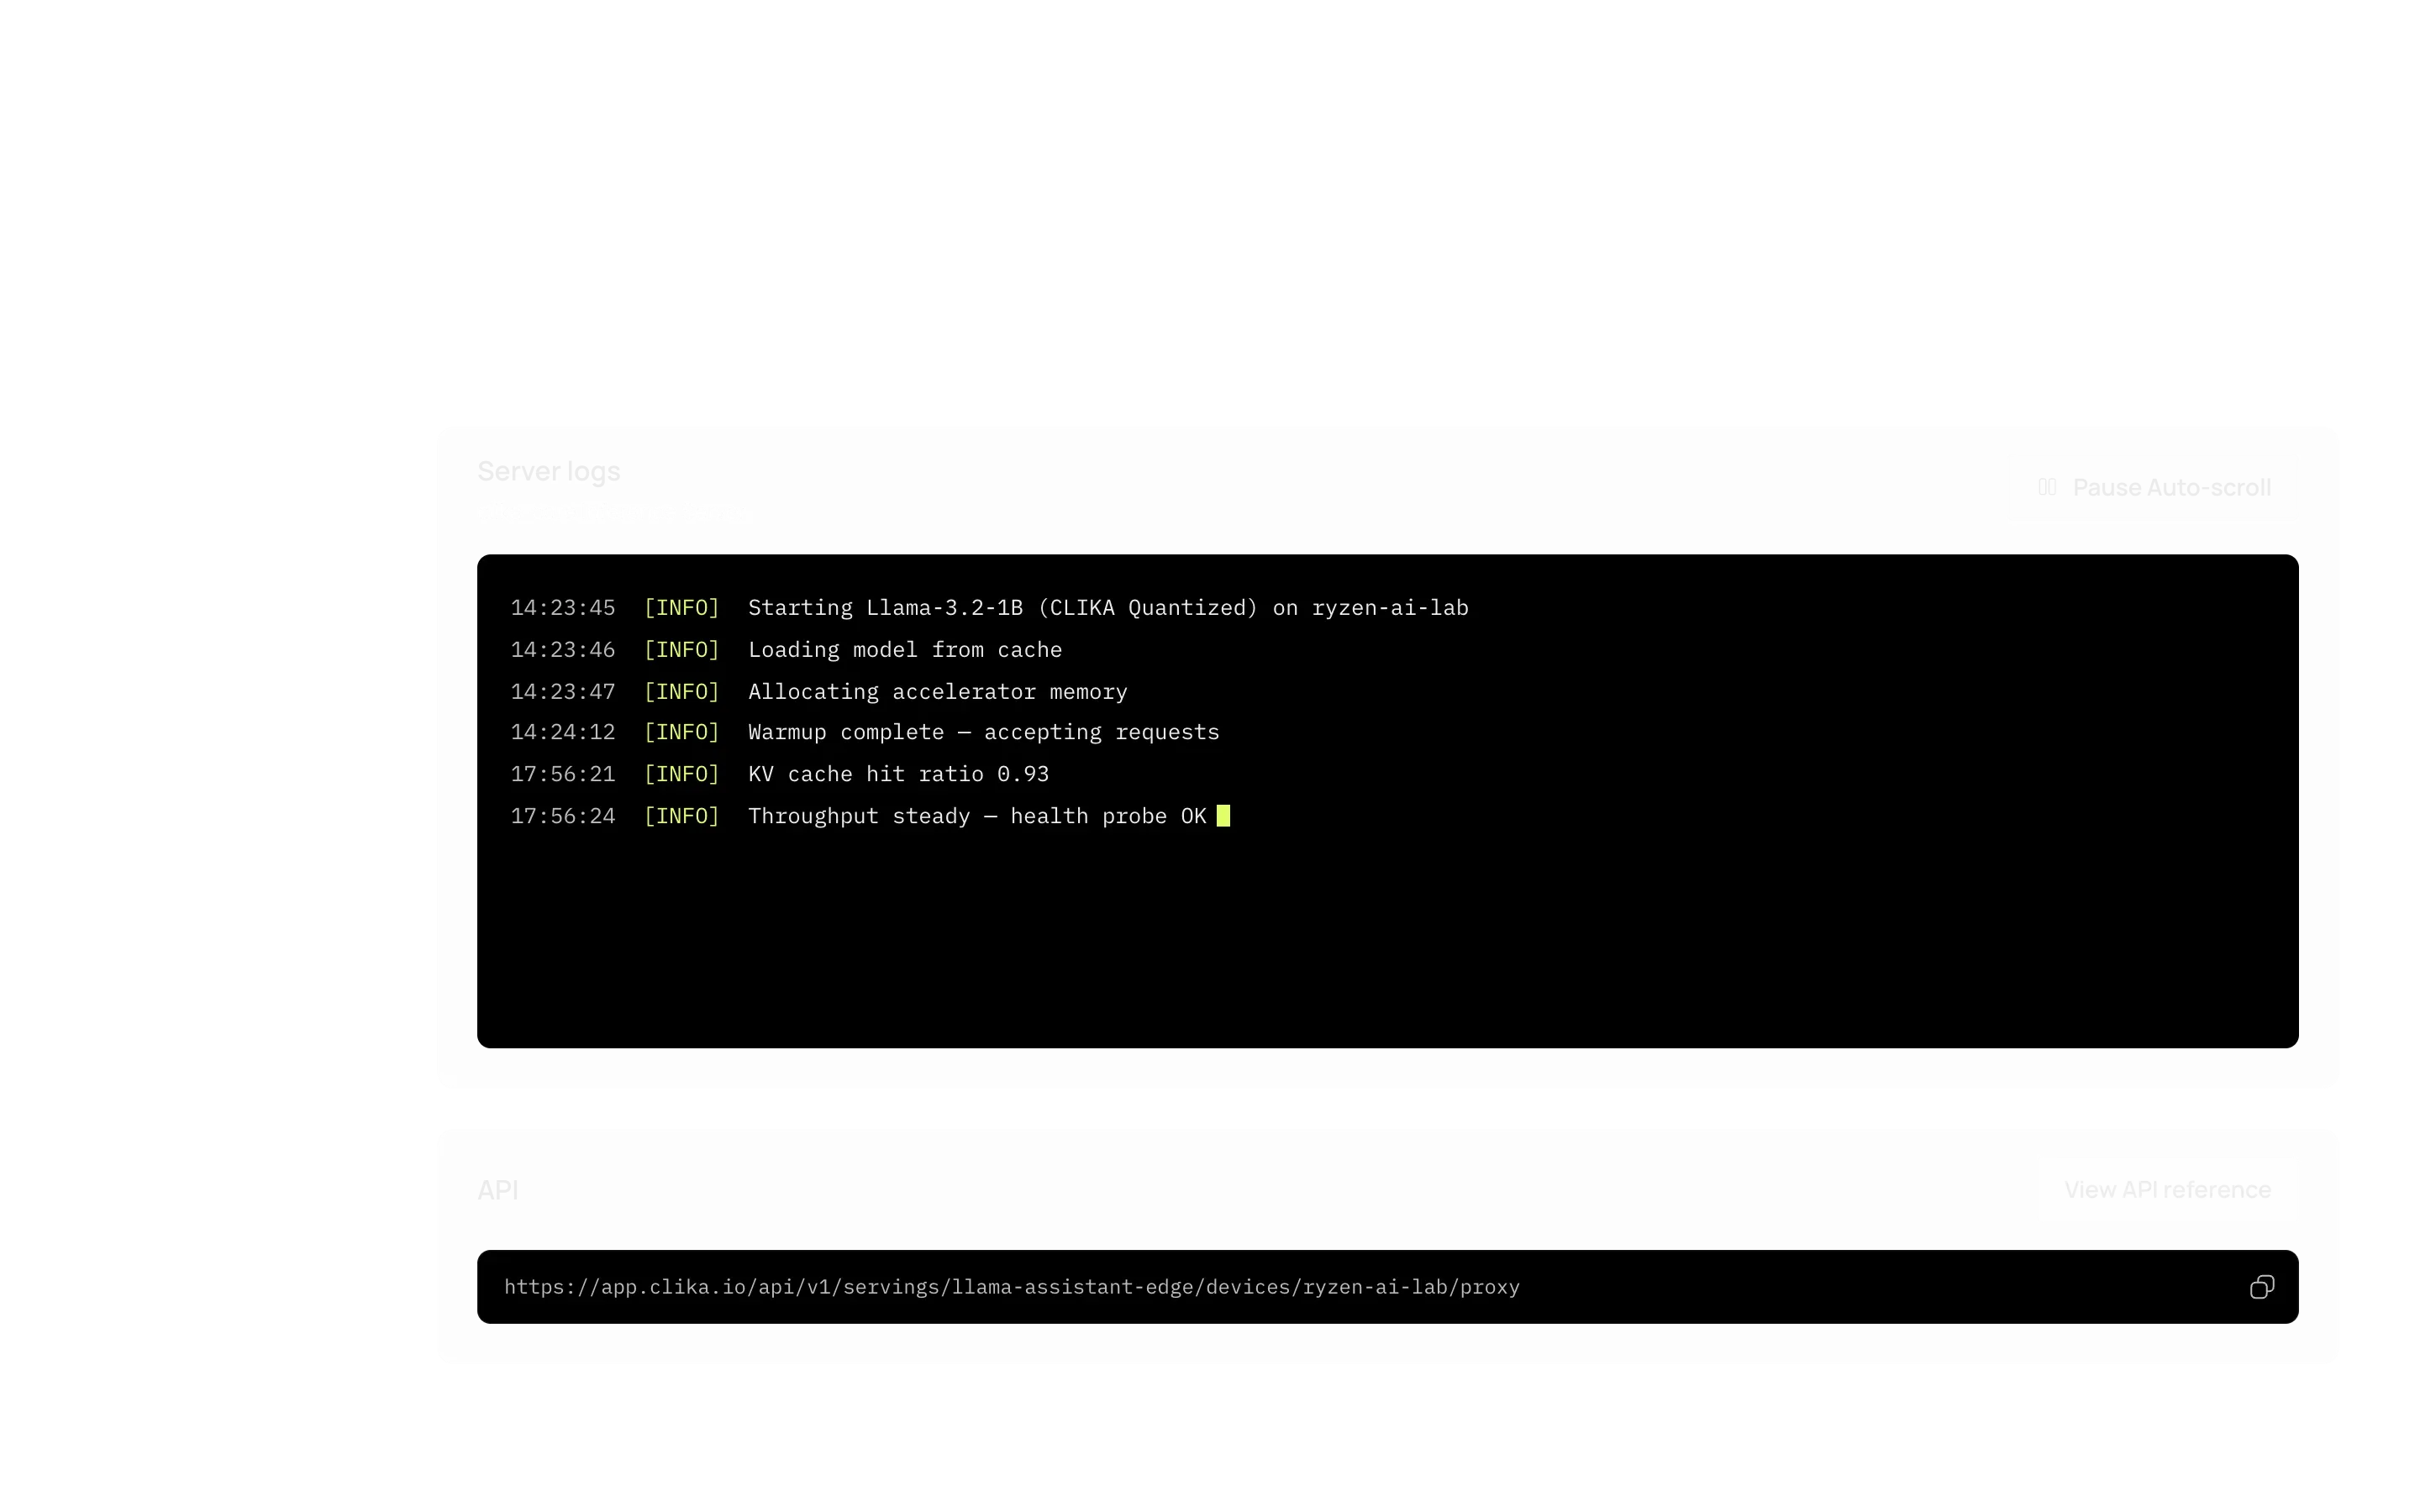
Every deployment gets its own endpoint, with a reference made for its model type: chat, transcription, images and more. Test it in the browser before you write any code.
Keep it running
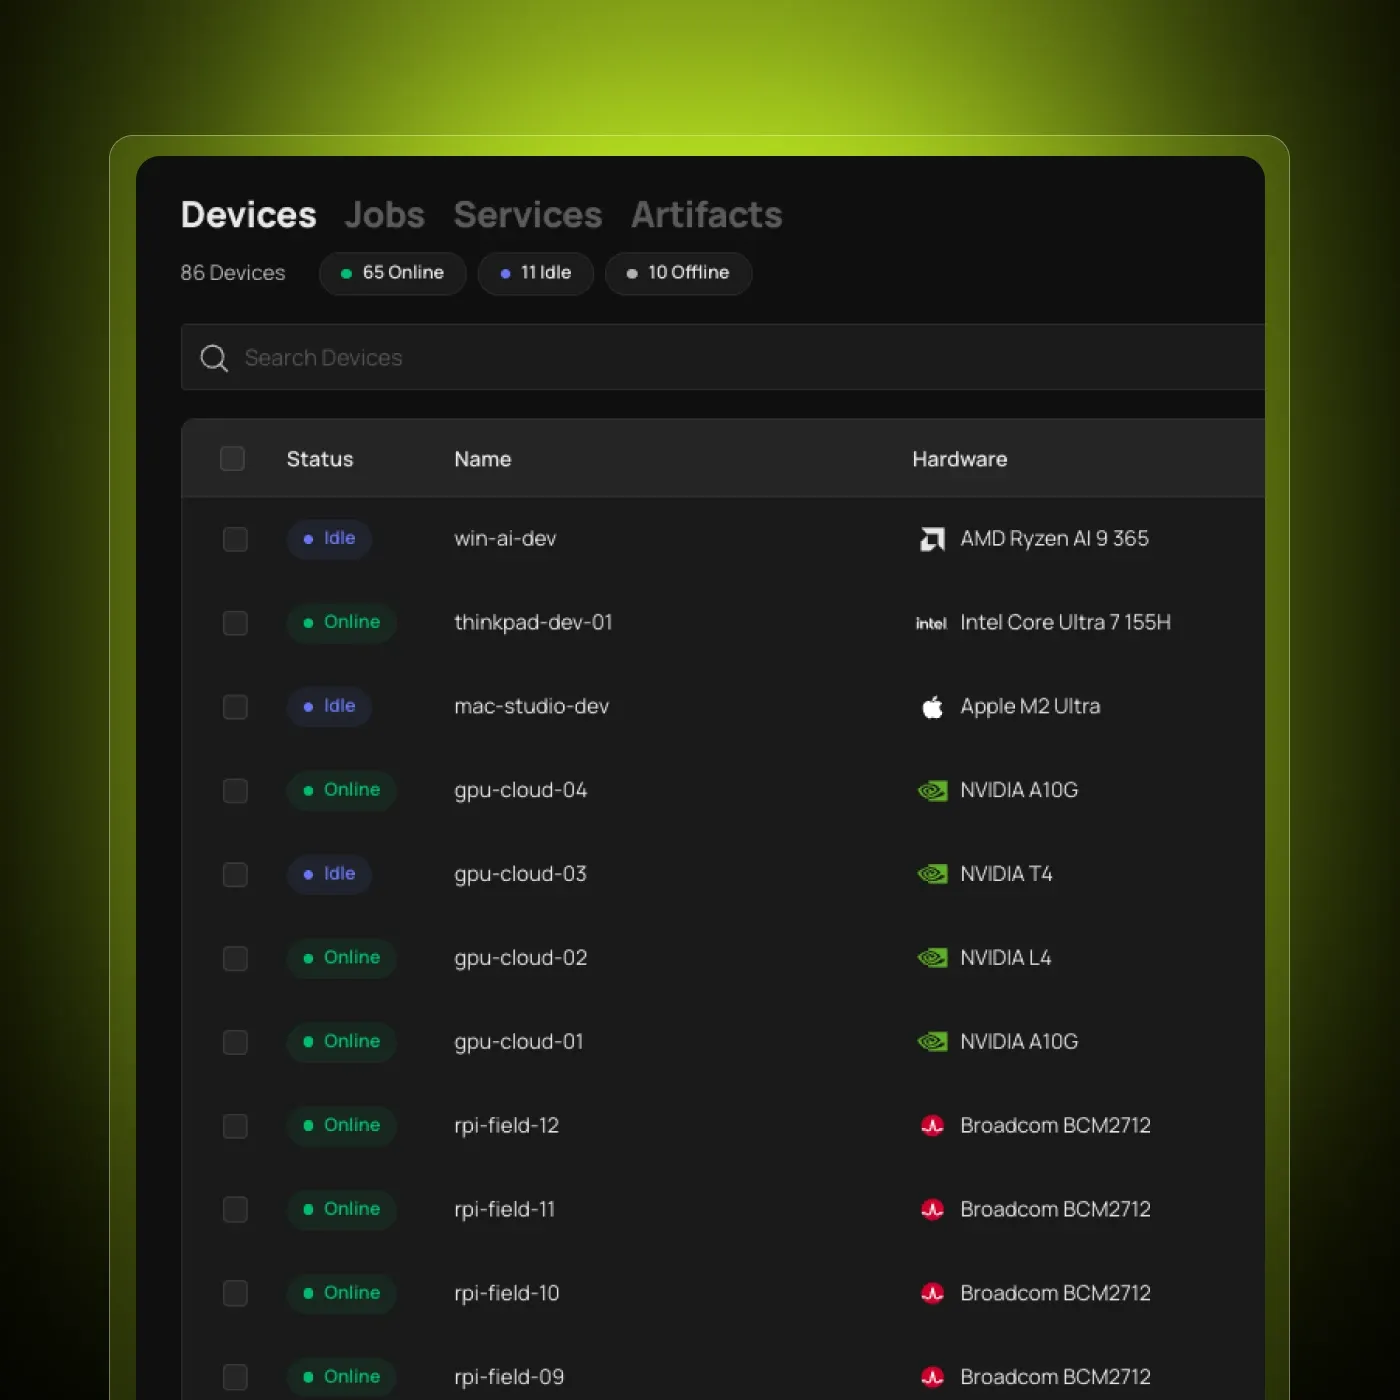
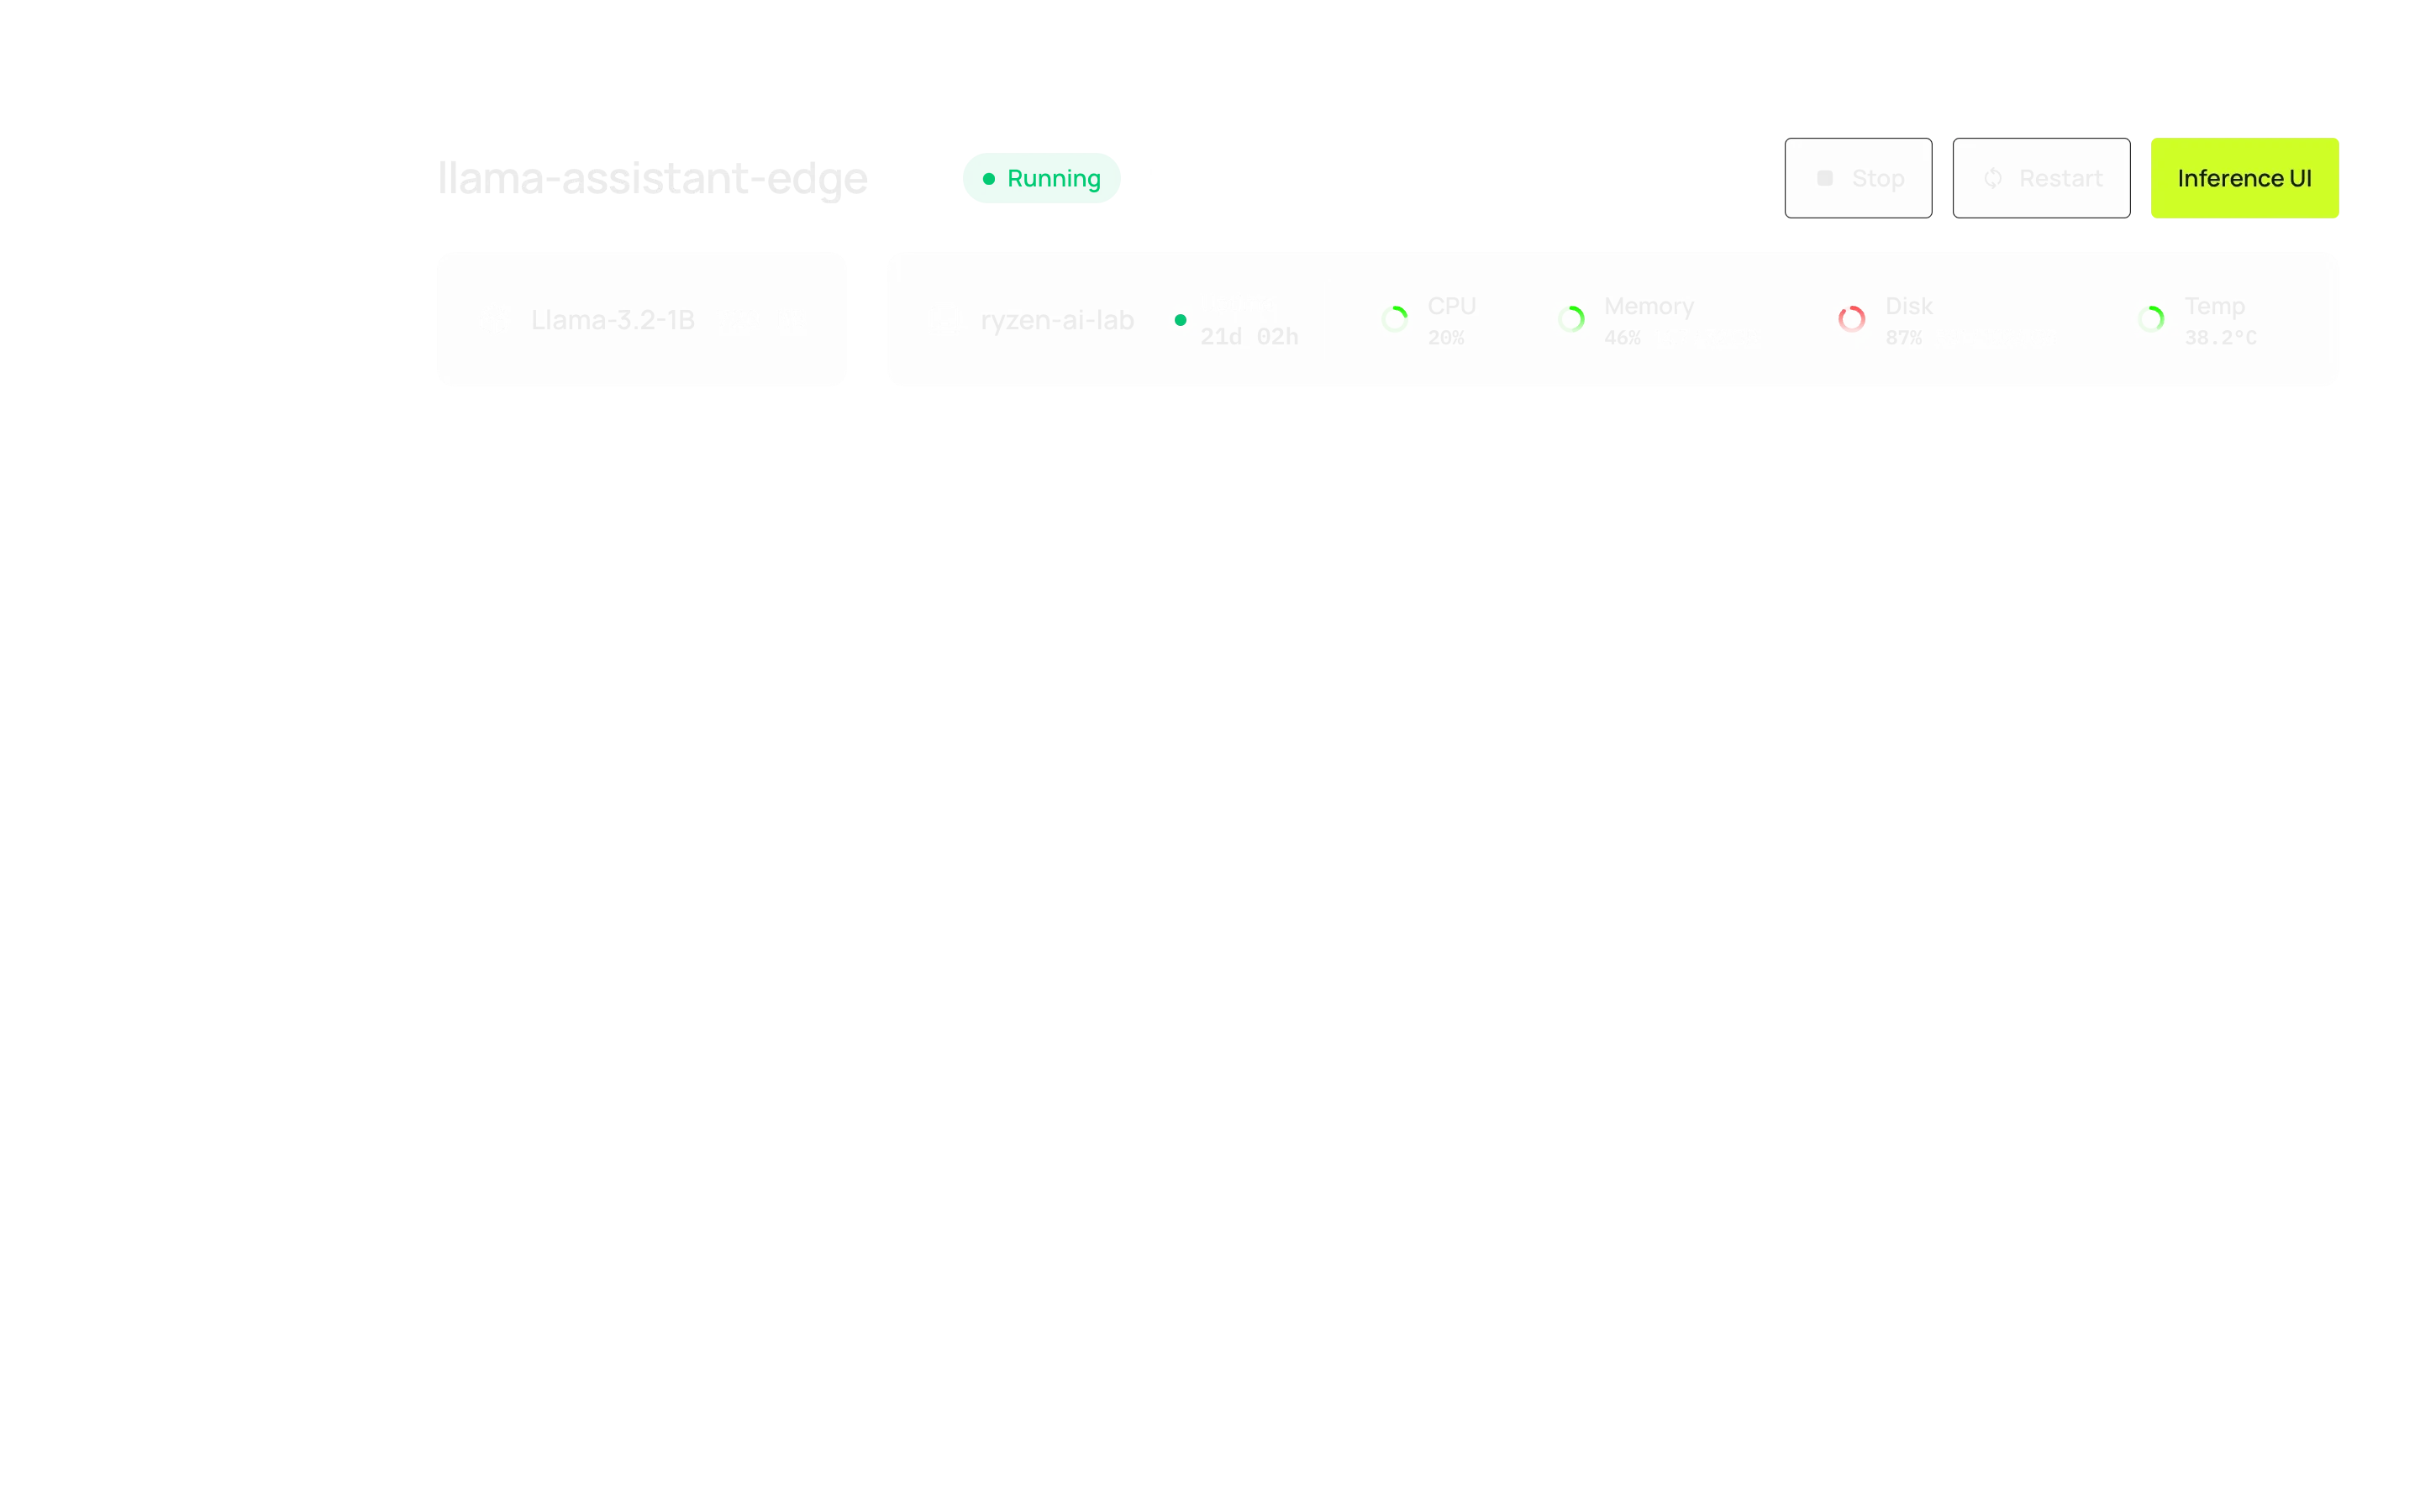
See what runs on which device, with its status and where it was started. Stop, start or restart any deployment from one list, across your whole fleet.
Explore Device ManagementLeave your email and we will get you in.